RAG chatbot for a UAE travel agency on the website, WhatsApp, Instagram and Messenger: streaming answers, voice, lead capture, a 24-hour follow-up email and Stripe subscription billing.
- My role
- Sole engineer — architecture, RAG pipeline, backend, widget, billing
- Links
- Live site ↗GitHub ↗
- Stack
- ClaudePostgreSQLSupabaseNode.jsFastAPIPythonStripeWhatsApp
- Claude API · Voyage embeddings · pgvector · Supabase · Node.js · FastAPI (demo) · Stripe · WhatsApp Cloud API
- Microsoft-ecosystem fit
▸ Copilot-style assistant pattern
▸ Responsible AI: grounded answers, citations, human hand-off
▸ Accessibility: Arabic/English, keyboard-operable chat
4
Channels, one retrieval brain
11/11
Demo API tests passing
[REPLACE]
Leads captured / month
Live demo
Ask Safira.
Streaming responses, conversation memory and cited sources. API keys stay server-side; when the model is unavailable, the assistant answers from retrieved sources only and labels the response.
Safira
Safarnama Global · grounded answers
Ask about Safarnama Global's services. Responses are generated only from the company's content and include sources.
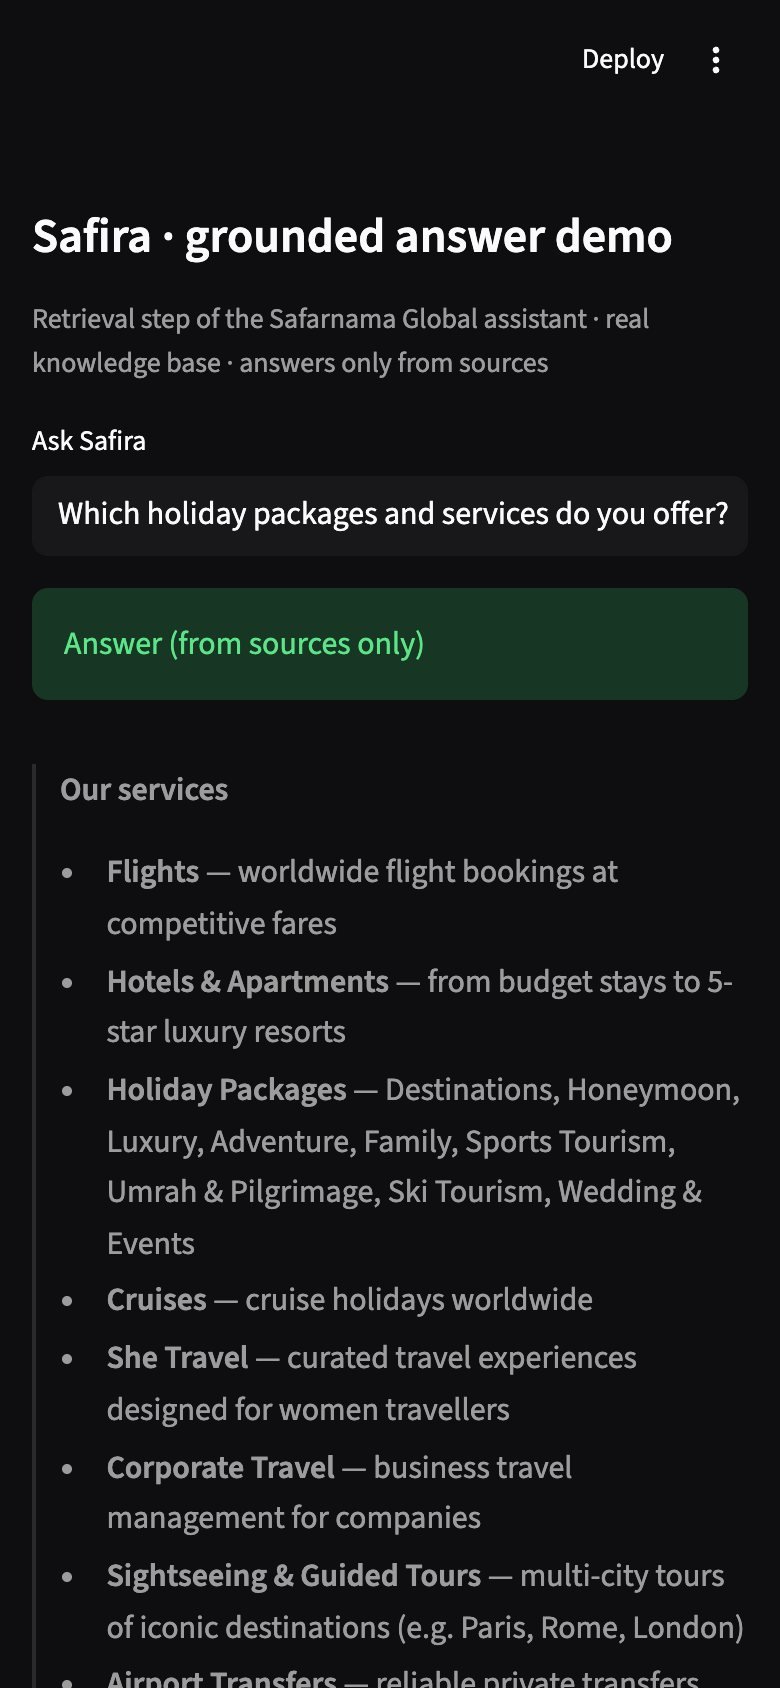
Source · Streamlit demo of the retrieval step on Safarnama's real knowledge base
01 — Problem
Customer enquiries arrived around the clock in Arabic and English across four channels, and staff answered repetitive questions manually.
02 — Approach
- 01
Embedded the agency's pages into pgvector (Voyage, 1024-d); Claude answers only from retrieved chunks, citing them.
- 02
Bilingual by design: replies in the visitor's language, streams tokens, supports voice in and out.
- 03
Lead capture inside the conversation → email + webhook to CRM → follow-up email at hour 24.
- 04
Below a confidence floor it hands over to a human on WhatsApp instead of guessing.
03 — Architecture
System architecture
S01
Web · WhatsApp · IG · Messenger
S02
Channel router
S03
Embed query
S04
pgvector top-k
S05
Claude · streaming
S06
Leads → CRM
04 — Engineering notes
Retrieval, in the database
The knowledge base lives next to the conversations in Supabase. Similarity search is one SQL function, so the API stays thin and the ranking is testable on its own.
-- server/sql/schema.sql (production)
create or replace function match_documents (
  query_embedding vector(1024),
  match_count     int default 5,
  filter_lang     text default null
)
returns table (id bigint, content text, lang text, source text, similarity float)
language sql stable
as $$
  select d.id, d.content, d.lang, d.source,
         1 - (d.embedding <=> query_embedding) as similarity
  from documents d
  where filter_lang is null or d.lang = filter_lang
  order by d.embedding <=> query_embedding
  limit match_count;
$$;
Both languages are searched on purpose. A question in Arabic can be answered from an English page, and Claude replies in the visitor's language.
Grounding as a rule, not a hope
If the sources don't cover it, Safira says so and offers WhatsApp. It never quotes a price it didn't retrieve.
The demo in demos/safira_grounded_chat shows that contract with a confidence floor: below it, the assistant hands the visitor to a human instead of answering.
The live demo on this page
The chat above calls a server route, so the key never reaches the browser. With a key configured, the FastAPI service streams Claude's answer from retrieved sources. Without one, or if the model is down, it degrades to retrieval-only answers instead of failing.
# services/safira-api/app/llm.py
async with self.client.beta.messages.stream(
    model=MODEL,                      # claude-opus-5-5
    max_tokens=2048,
    system=SYSTEM,                    # answer only from numbered sources, cite [n]
    messages=messages,
    output_config={"effort": "low"},  # chat: fast first token
    betas=["server-side-fallback-2026-07-01"],
    fallbacks="default",
) as stream:
    async for text in stream.text_stream:
        yield text
Rate limiting (a per-IP token bucket), input caps, history trimming and the offline fallback are all covered by the service's 11 automated tests.
Outcome
Customers receive grounded answers at any hour, and qualified leads reach the sales team automatically.
Next project
LMS Portal