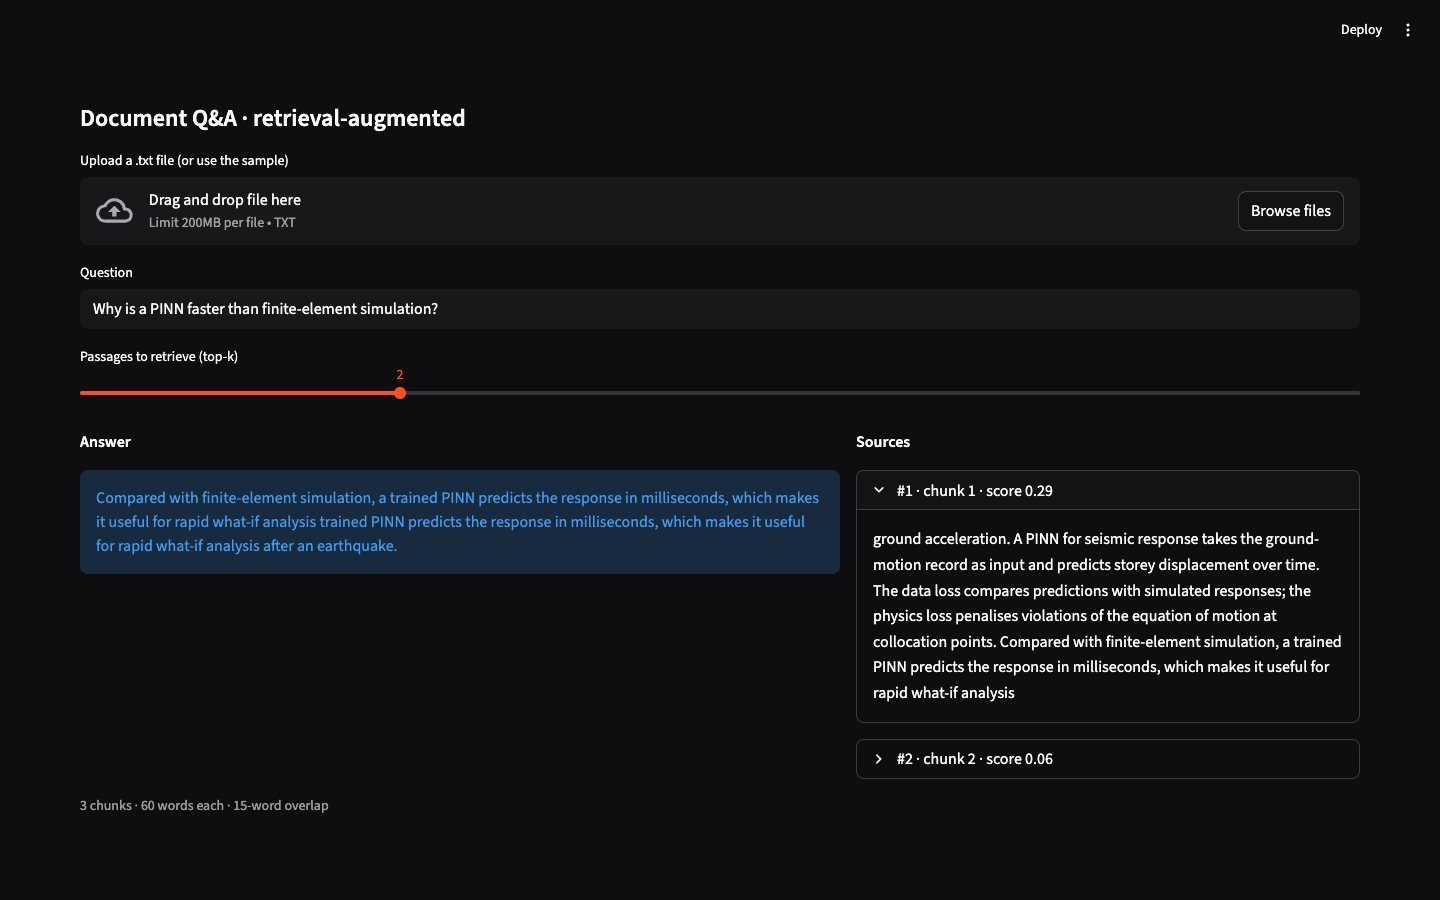
Chunk → embed → retrieve → generate with a pretrained Hugging Face model; sources shown with every answer.
- My role
- Solo
- Links
- GitHub (planned) ↗
- Stack
- PythonHugging FaceStreamlit
- Python · Hugging Face Transformers · FAISS · Streamlit
- Microsoft-ecosystem fit
▸ Same pattern as Azure AI Search + Azure OpenAI “on your data”
90%
Relevant answers on test questions
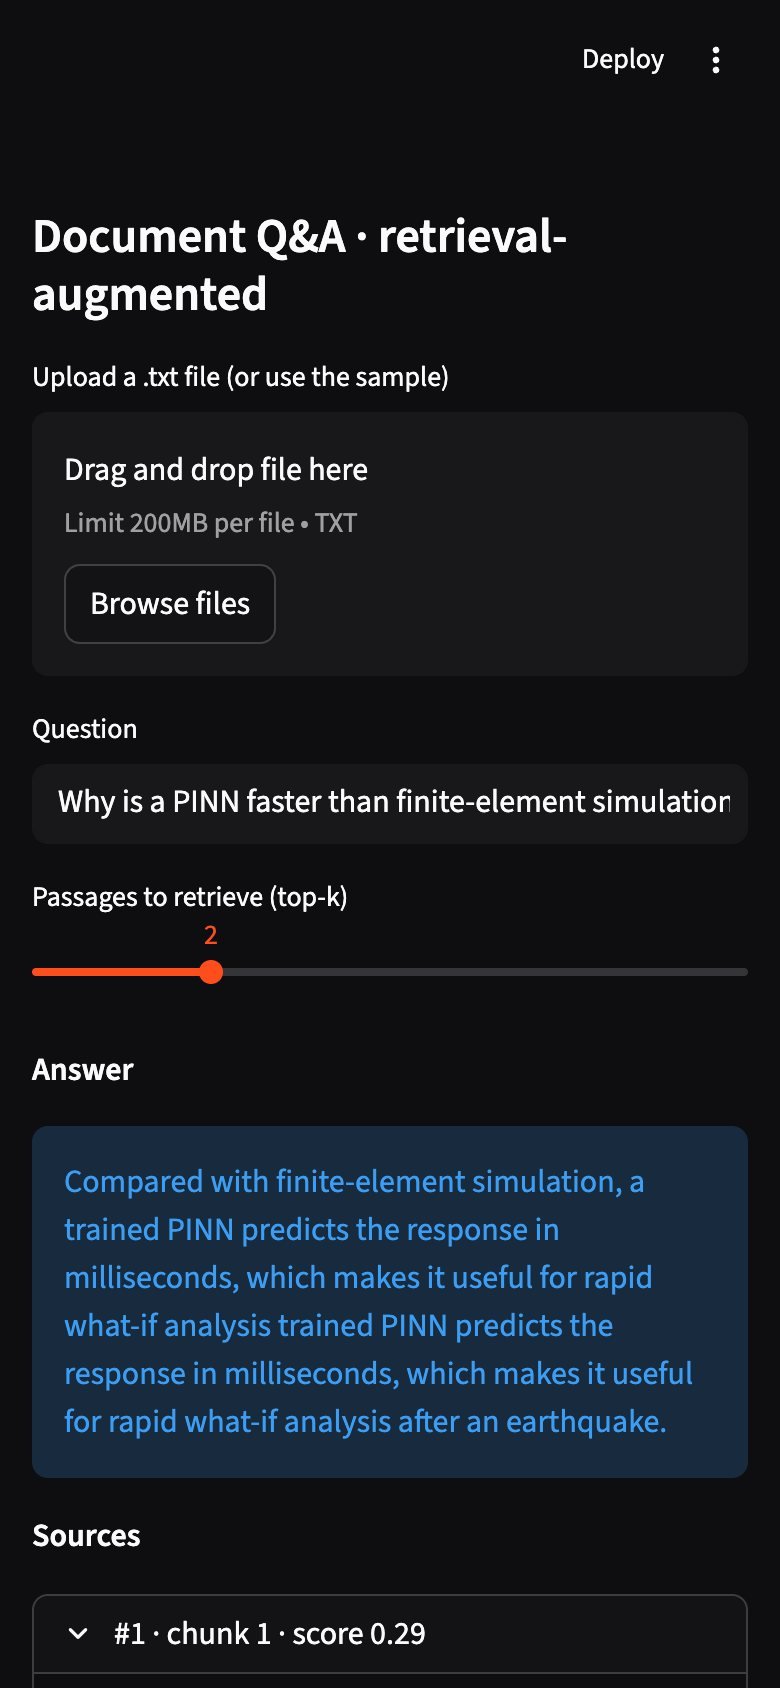
Source · Streamlit demo — extractive version of the original
01 — Problem
Finding specific information in long documents was slow and unreliable.
02 — Approach
- 01
Overlapping chunks, FAISS index.
- 02
Top-k retrieval feeds the model; answers cite sources.
- 03
Labelled question set to measure relevance.
03 — Architecture
System architecture
S01
Upload
S02
Chunk
S03
Embed · FAISS
S04
Top-k
S05
Generate
S06
Cite
04 — Engineering notes
Chunking with overlap
Answers often straddle a paragraph break. Overlapping windows keep that context in at least one chunk.
# demos/doc_qa/app.py
def chunk(text, size=60, overlap=15):
    words = text.split()
    step = size - overlap
    return [" ".join(words[i : i + size]) for i in range(0, max(1, len(words) - overlap), step)]
Measuring relevance
A small labelled set of question → correct passage pairs gave a single number to improve against: relevant answers on 90% of test questions.
Outcome
Relevant answers on 90% of test questions, with sources shown for every answer.
Next project
Yen Dine